Once, I was at a civic tech dinner convened by an organization trying to improve relationships between the executive and legislative branches.
This may sound crazy to anyone who has not worked in or around government, but the two branches don’t actually interact that much.
As we went around the table, the host asked everyone to name a quick fix or simply something they wished existed. One former administration official said he thought it would be useful if every new law came with a list of what each agency was supposed to do.
umm.. what?
He explained that there often is no clean, authoritative implementation checklist. Agencies may have to CTRL+F through hundreds of pages of legislative text to determine whether they are mentioned and what Congress has directed them to do.
And it is not unheard of for an executive branch agency to discover that it has a statutory obligation only after someone in Congress sends a letter asking where the required rule, report, program, study, or other deliverable is.
Oops.
This is one of those insanely broken systems that generative AI makes relatively straightforward to improve.
From enacted text to an implementation map
To demonstrate what is now possible, I took the recently enacted H.R. 6644, the 21st Century ROAD to Housing Act, and asked Claude and Codex to help me design and build an implementation dashboard.
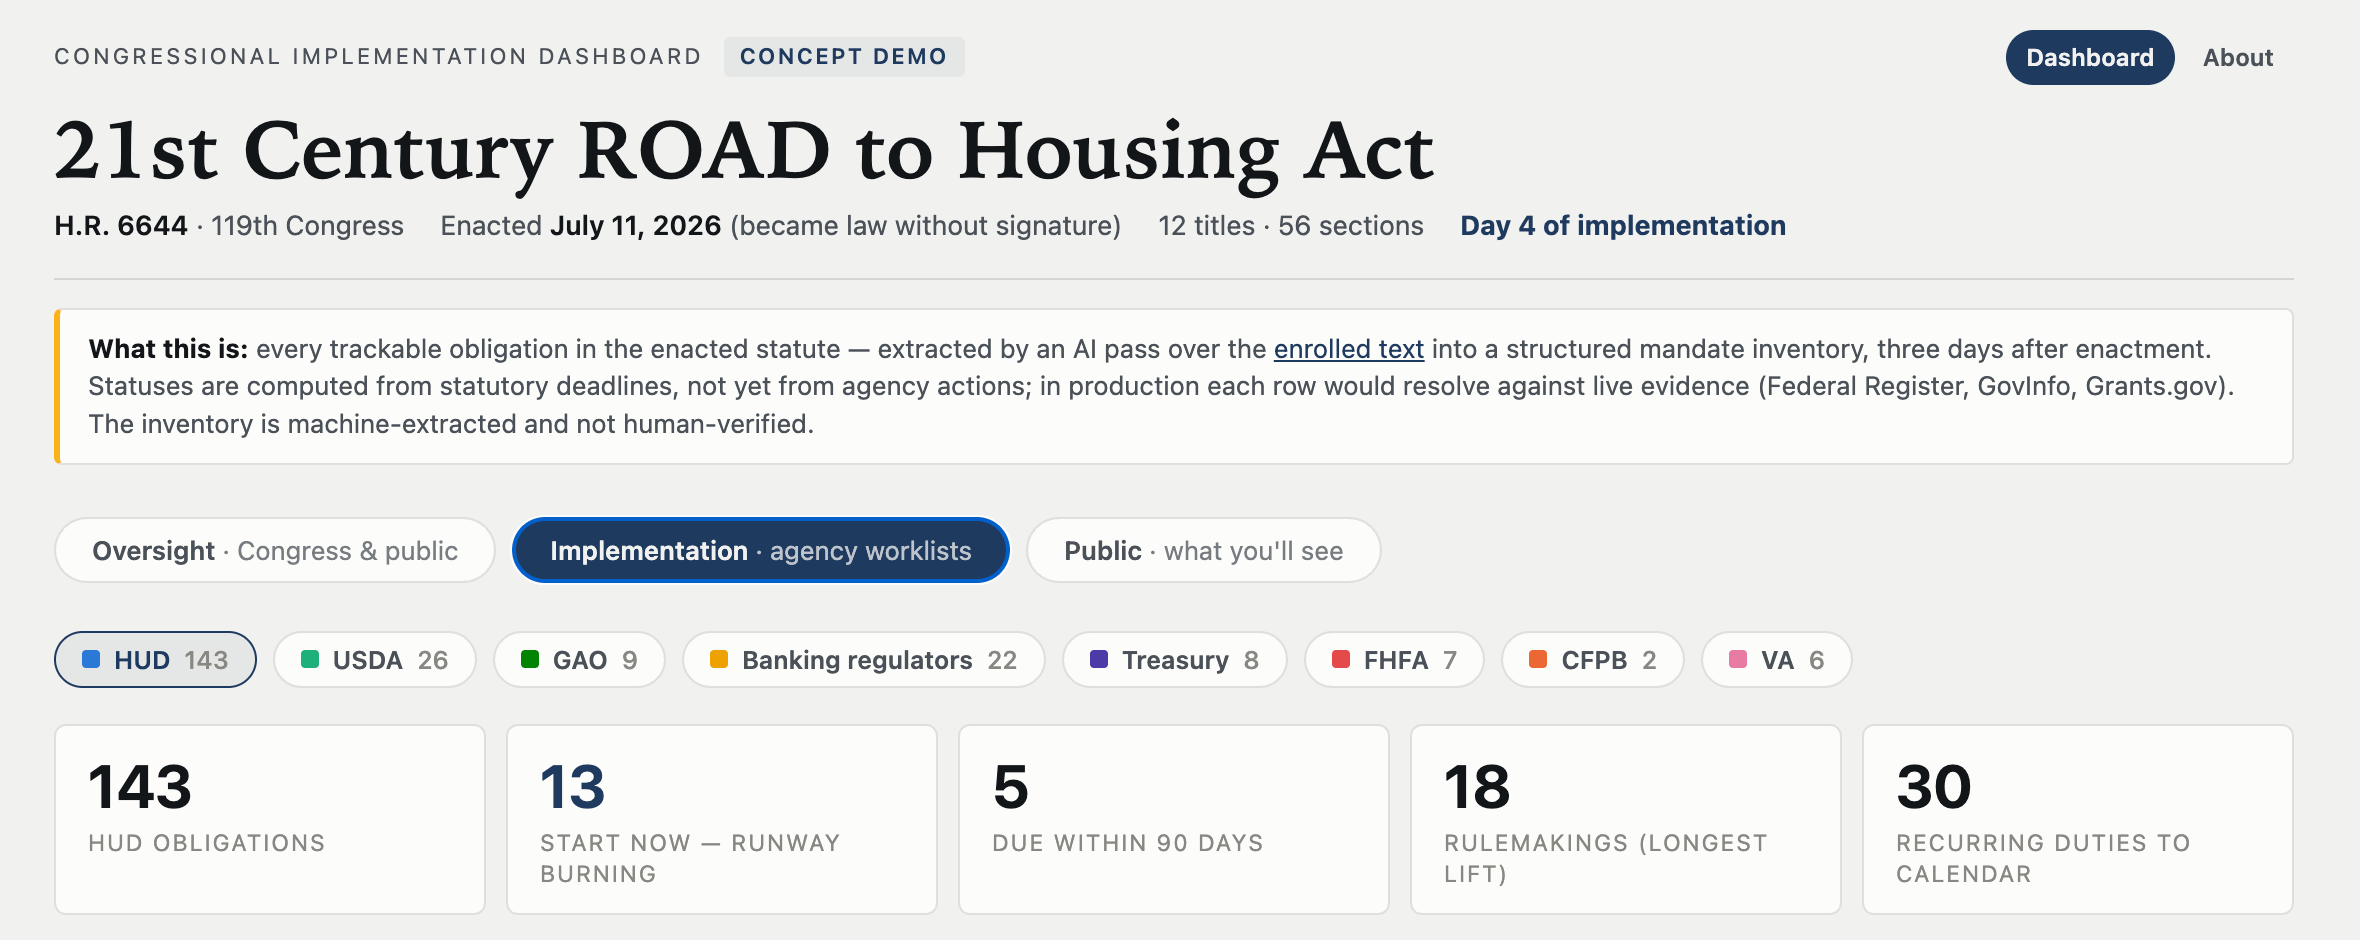
The law took effect on July 11, 2026, without the President’s signature. It is an enormous, bipartisan housing package that creates and modifies programs across HUD, USDA, the banking regulators, Treasury, VA, GAO, FHFA, and other parts of government.
The resulting dashboard is just a prototype and a work in progress. But even in its vibe-coded state, it demonstrates how much useful public infrastructure can be produced from legislative text.
The prototype extracted 208 potentially trackable obligations from the enacted text, including:
The actor responsible for carrying out each obligation
The required rule, report, study, grant, program, enforcement action, or other deliverable
The relevant statutory citation
Any deadline or recurring schedule
The underlying legislative language
The kind of public evidence that could eventually demonstrate implementation
Those records drive three different views.
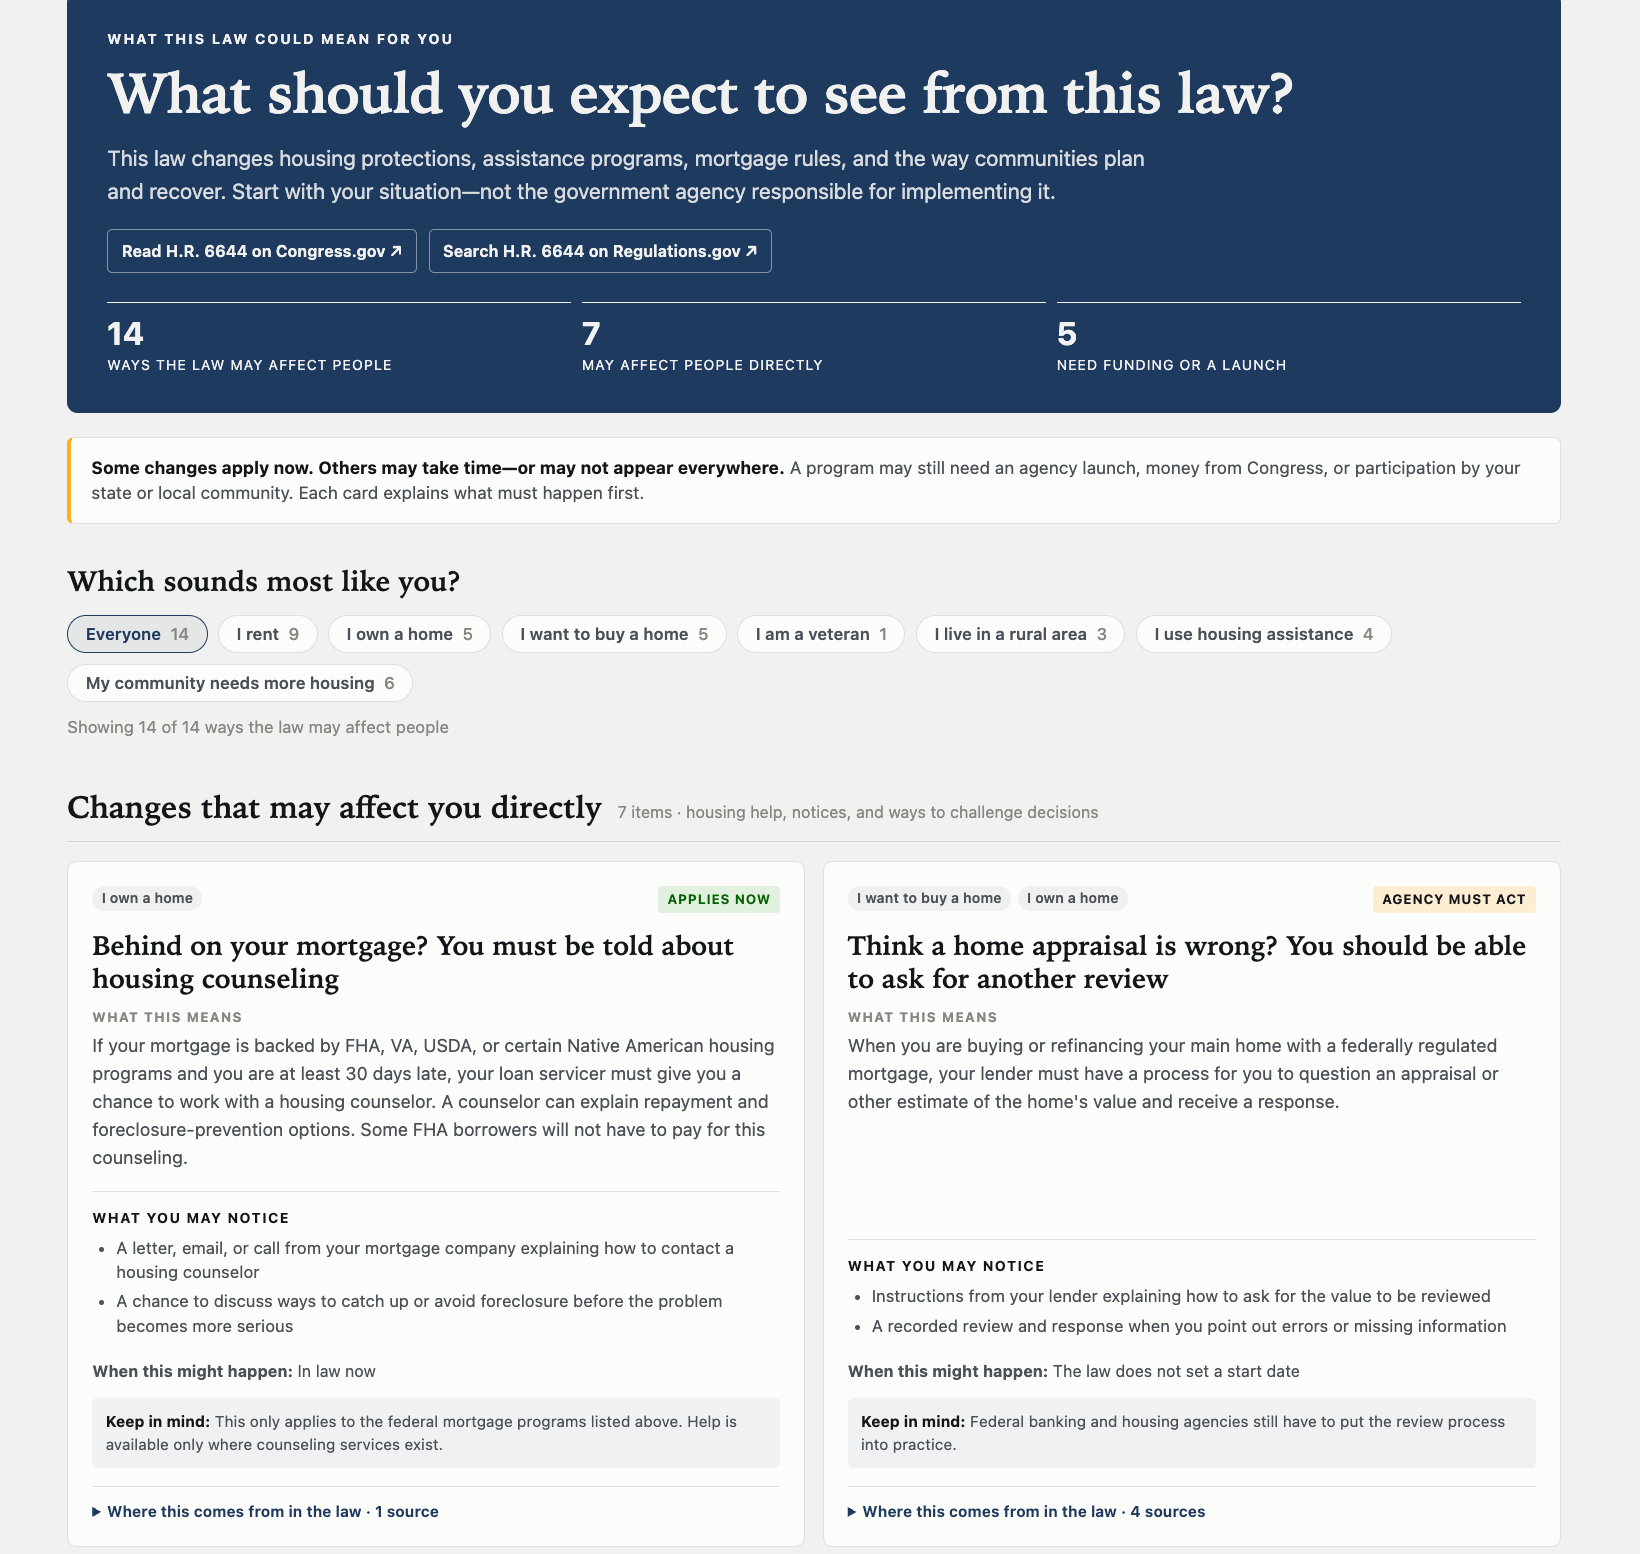
The Public view asks: What could this law mean for me? It translates selected provisions into descriptions for renters, homeowners, homebuyers, veterans, rural residents, people using housing assistance, and communities that need more housing.
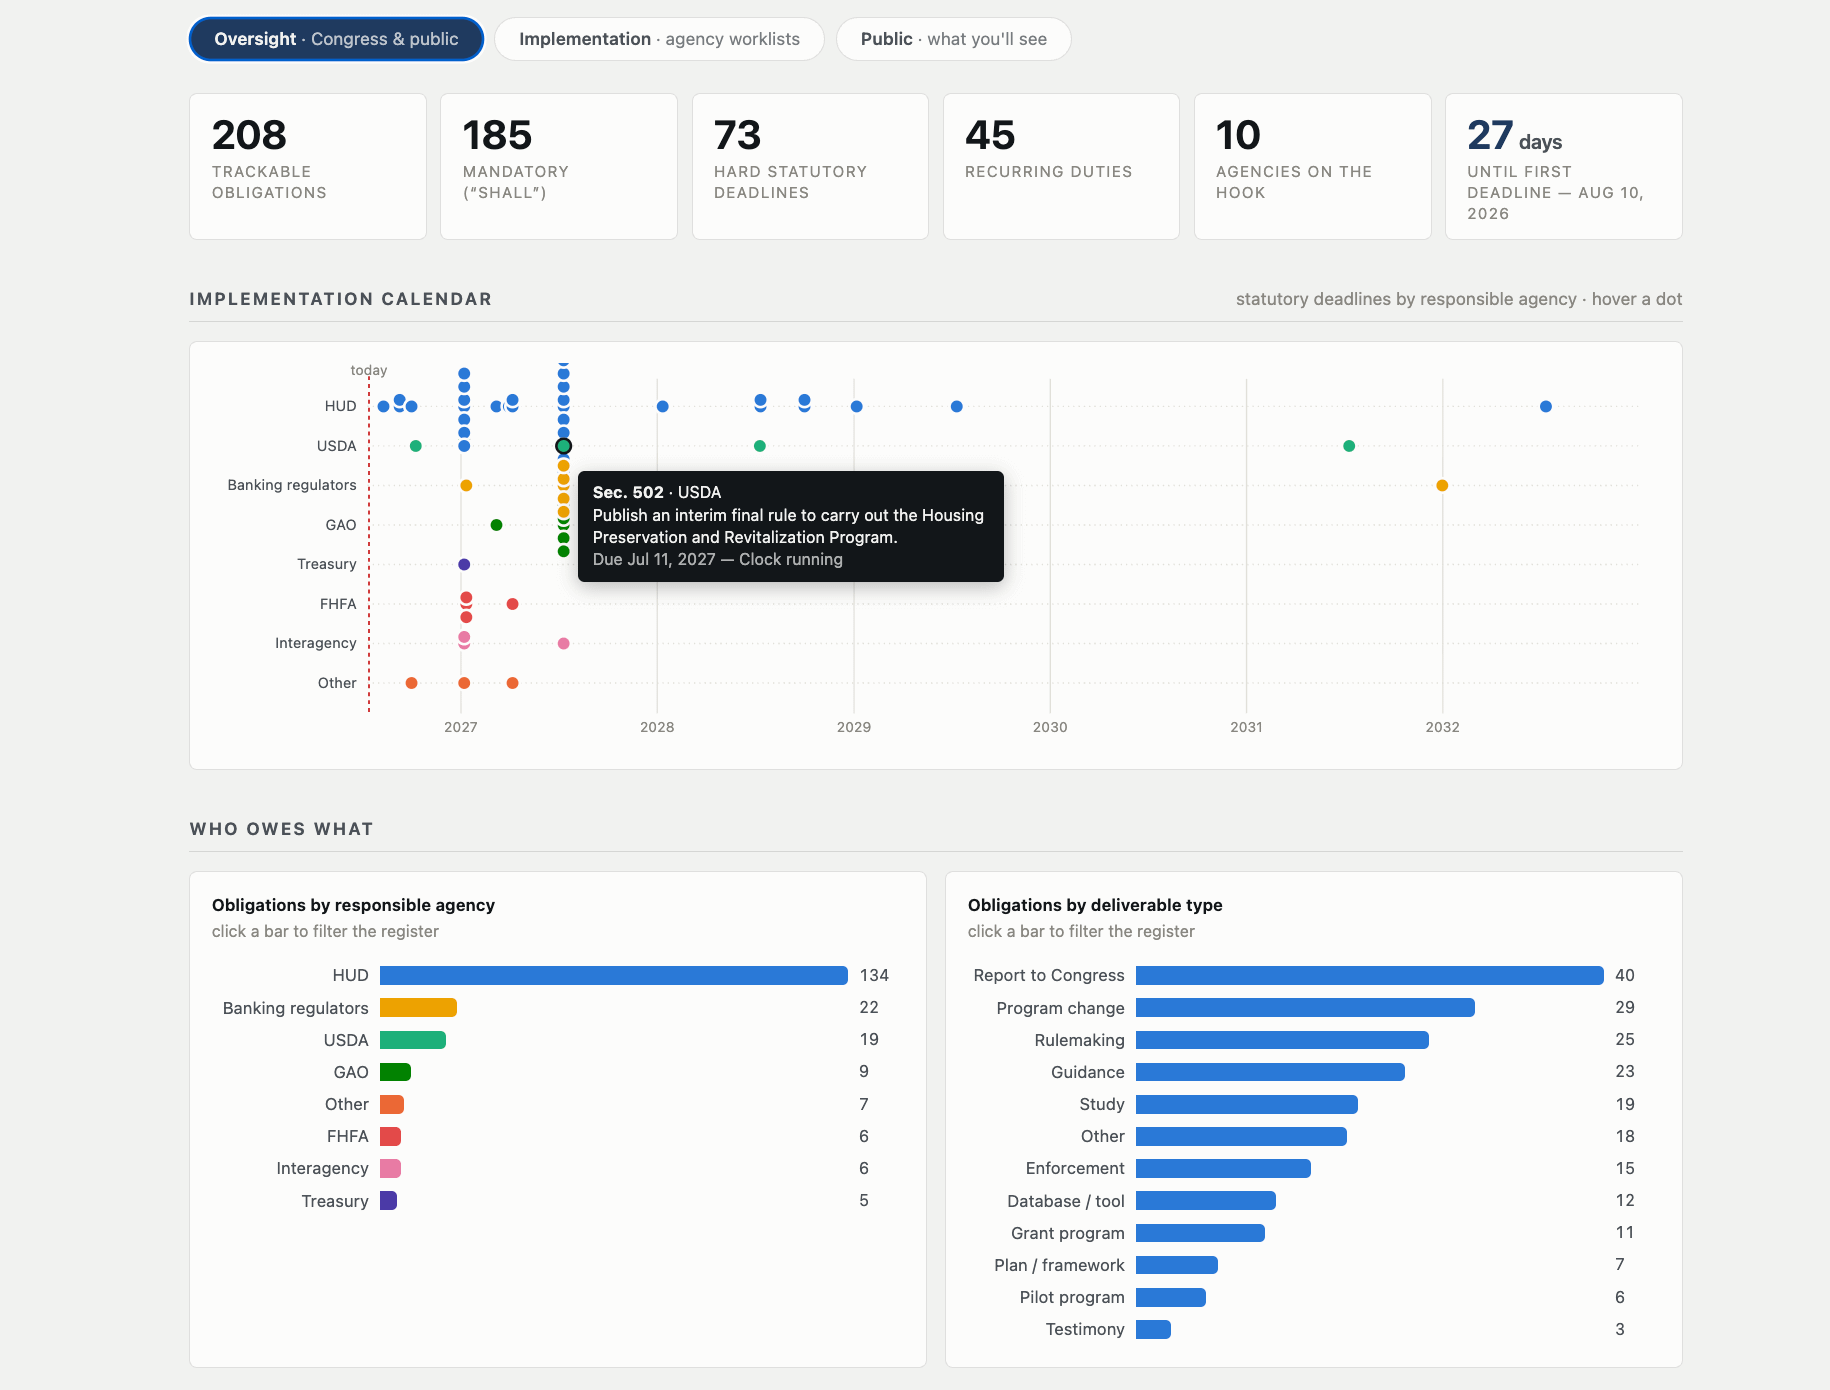
The Oversight view asks: What should Congress and the public be watching? It shows deadlines, recurring duties, responsible agencies, and the full mandate inventory.
The Implementation view asks: What does each agency need to do—and when should the work begin? It converts statutory deadlines into an illustrative operational work queue.
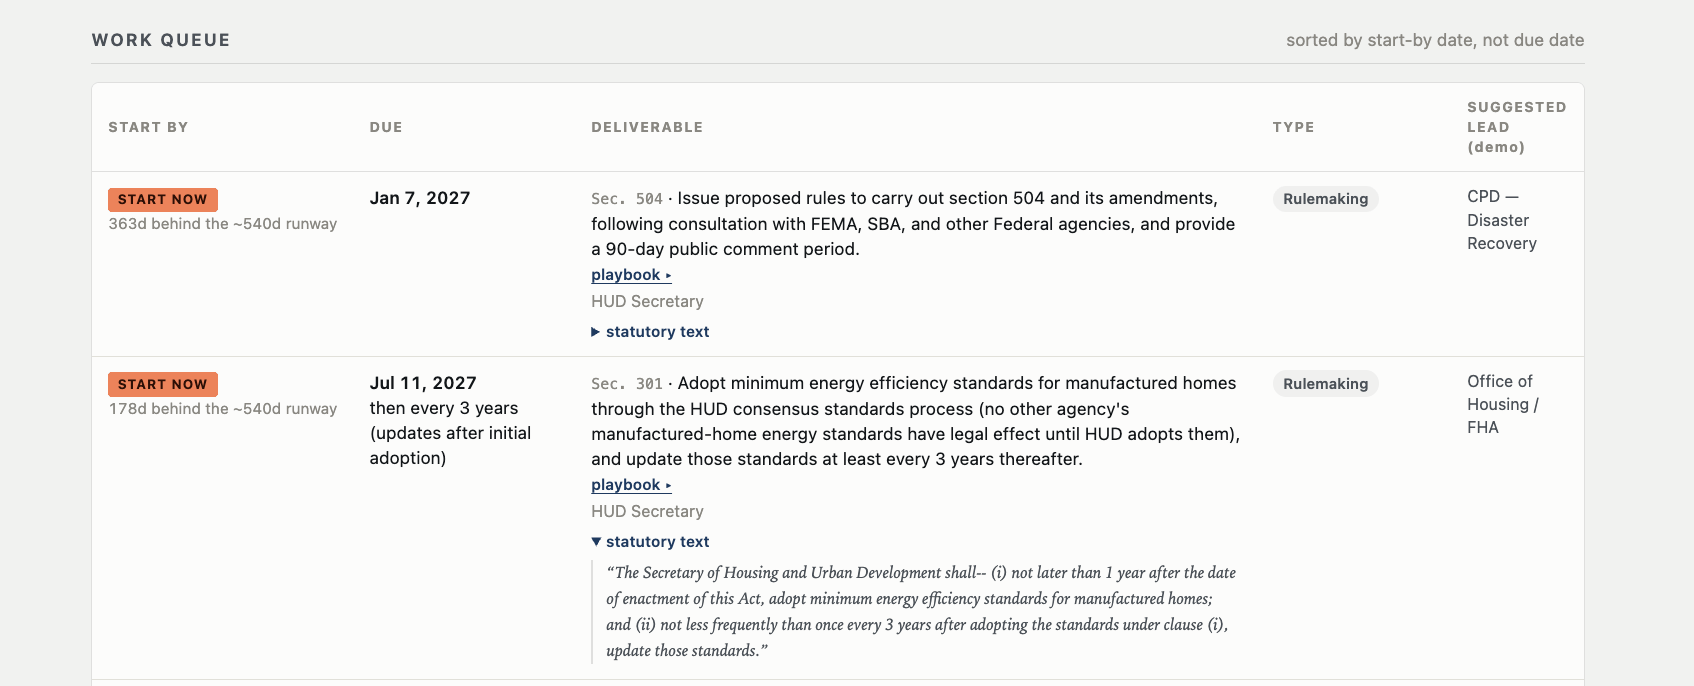
Every underlying quotation is mechanically checked against the enrolled text. That does not make the interpretation authoritative: the extraction, obligation boundaries, deadlines, and public explanations still require human review. But it creates a far stronger starting point than a PDF, a search box, and institutional memory.
This housing law is also a data law
The dashboard focuses on implementation obligations, but the law itself makes a broader point: effective housing policy increasingly depends on better public data.
The Data Foundation’s Avery Freeman explores this in an excellent analysis, “What the Bipartisan Housing Bill Means for Data Policy.”
Among other things, the law calls for:
Searchable public information about vacant land owned by local governments
Block-level housing-production data tied to some federal funding decisions
Reporting across 22 categories of local zoning policy
A temperature-sensor pilot that could create evidence of unsafe conditions in assisted housing
Better reporting about large institutional investors that own single-family homes
As the Data Foundation notes, the law takes real steps toward a national housing-data infrastructure. It also exposes persistent gaps—including the lack of a comprehensive national system for determining who owns single-family homes.
That matters because implementation cannot be separated from data. A legal requirement is only meaningfully trackable if we know what evidence it should produce, where that evidence will appear, and how the public can access it.
From a prototype to public infrastructure
This prototype still required a custom extraction process, a custom data structure, editorial judgment, and multiple rounds of interface design. That is manageable for a demonstration. It is not how we create implementation dashboards for every new law, across every jurisdiction.
This is where the Axiom Foundation’s work becomes especially important.
Axiom is developing open rules-as-code infrastructure for turning statutes, regulations, and policy rules into machine-readable encodings. Its model preserves citations and effective dates while making rules computable and auditable. Its open infrastructure is intended to work across federal statutes, federal regulations, agency guidance, and state law.
That shared layer could make tools like this far easier to deploy at scale.
Instead of every agency, civic technologist, watchdog, or AI system translating a law independently, an open schema could allow the law to be encoded once and then used to generate many different public tools:
Implementation checklists
Deadline calendars
Oversight dashboards
Eligibility calculators
Public explainers
Compliance systems
Legislative amendment comparisons
Alerts when evidence of implementation appears—or fails to appear
The same underlying law could support different interfaces for agencies, congressional staff, journalists, researchers, advocates, and the public, without each group rebuilding the interpretation from scratch.
That is the promise of rules as code: not replacing legal text or human judgment, but giving institutions a shared, inspectable, machine-readable layer on which better systems can be built.
Institutional AI
I think of this as an example of Institutional AI: AI used to strengthen institutional capacity, accountability, and trust.
The most important applications of AI in government may not be chatbots or autonomous decision-makers. They may be tools that help institutions understand their own obligations, preserve institutional memory, coordinate across organizational boundaries, and make their work more legible to the public.
A law should not disappear into the machinery of government after enactment.
Agencies should be able to see what they owe. Congress should be able to see what it needs to oversee. Members of the public should be able to understand what the law may change for them. And everyone should be able to trace those claims back to the actual statutory text.
We will have much more to say about Institutional AI soon.
In the meantime, please check out the prototype and leave a comment with feedback, suggestions, or questions. What would make this more useful? What is still confusing? And what other laws (or jurisdictions) should have an implementation dashboard like this?
Marci Harris is Co-founder and CEO of POPVOX, Inc. and Executive Director of the POPVOX Foundation, which works on congressional modernization and legislative technology. She is a lawyer and a former congressional staffer and a Futures Fellow at the Harvard Kennedy School’s Ash Center for Democratic Governance and Innovation.
Really great content here.
This is fascinating! While labor intensive, have you considered running extracted data through a knowledge graph? It would have to be structured based on the policy domain area, but I think it could super charge the to do list